Choosing your signals
Once you have set up OpenTelemetry on Platon, the next question is when to add a metric, a log or a span. This page describes how the three signals relate and gives some heuristics for choosing between them.
The three signals
- Metrics are for anything you want to graph or alert on. They answer how often, how fast or how big something is, and they are cheap to aggregate across billions of events. A metric does not help you debug one specific request.
- Logs give a detailed account of what happened on a single request, which is what you need for error context, audit trails and investigation after the fact, but they are expensive to aggregate at scale.
- A trace is the timeline of one request, made up of spans, and it shows why that request was slow or how it moved across services. Traces are rarely read in bulk; you open one when a particular request has a problem.
The signals overlap: you can count log events, and you can put narrative text in a span attribute. But each signal has a different cost profile and is optimized for a different question.
Spans carry the context you filter and group traces by, and logs carry the account of what happened. Traces — Put context on your spans shows which goes where.
Practical heuristics
| You want to answer… | Use |
|---|---|
| "User 42 clicked enroll" (business event) | Log |
| "How many enrollments per minute?" | Metric (counter) |
| "What is the p95 of enrollment latency?" | Metric (histogram) |
| "Why is enrollment slow for course X today?" | Trace |
| "How many enrollments failed in the last hour?" | Metric counter, with logs for drill-down |
| "Did this request actually reach the eligibility-checker?" | Trace |
| "Show me every request that hit endpoint Y with status 500" | Trace search, with logs for drill-down |
| "Is our error rate climbing?" | Metric and alert |
Common anti-patterns
- Logging what should be a metric. Emitting
logger.info("order placed")for every order and then counting log lines is slow and expensive. Count the orders with a metric counter instead, and reserve the log line for a business-meaningful event with context. - Putting what should be a log in a metric label. Attaching
user_idas a metric label turns one time series into millions, and high cardinality is the most common way to overload a metrics backend. The user ID belongs in a log instead. See Metrics — Cardinality. - Putting bulk payload data in span attributes. Spans have attribute size limits, and Tempo query costs scale with span size, so an entire JSON request body, for example, does not belong in a span attribute.
- Alerting on log patterns instead of metrics. Alerts on log patterns break when the log format changes. They are also expensive, because searching Loki at scale is slow. Emit a metric when the event happens, and alert on the metric instead.
Correlating the three signals
When all three signals are wired up, you can move between them in four ways.
-
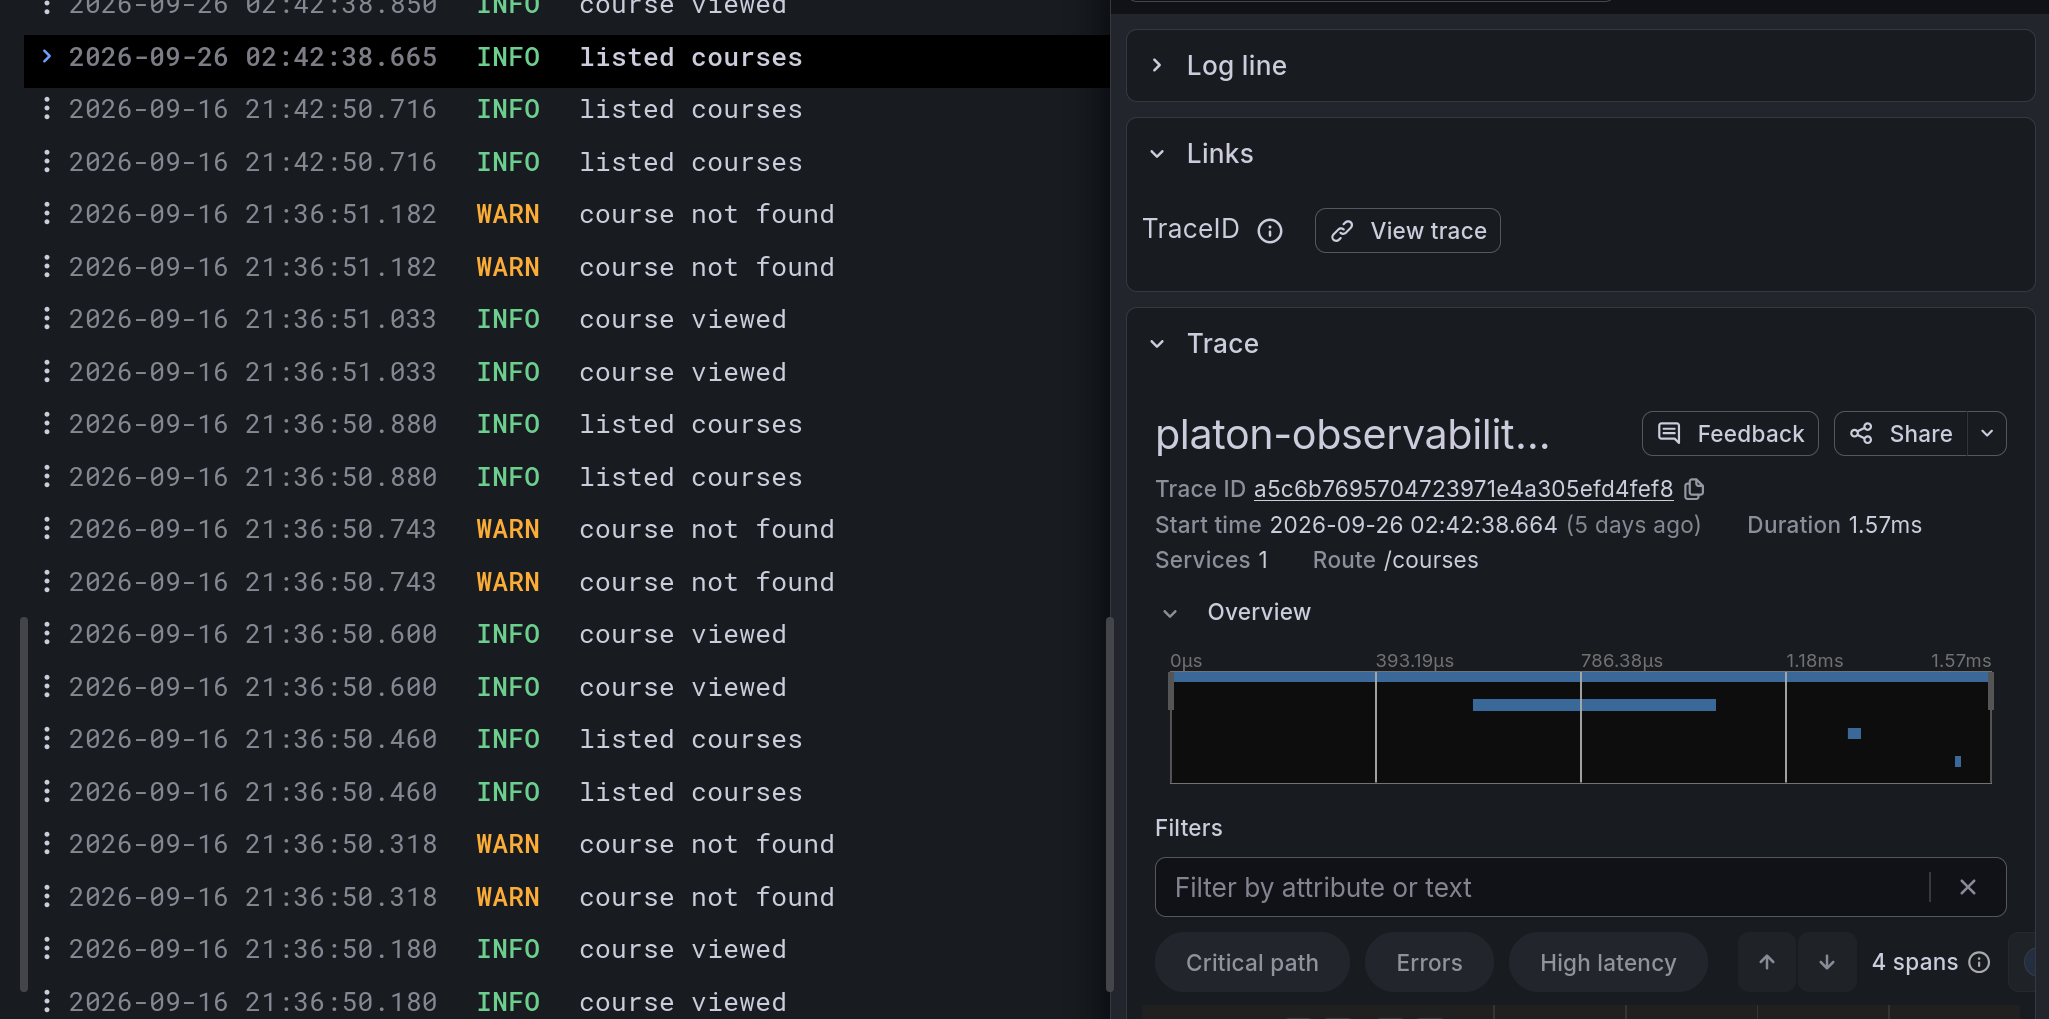
From a log line to its trace. Expand the line in Grafana's Loki view and click View trace under Links in the log details. The trace shows where the request spent its time.
-
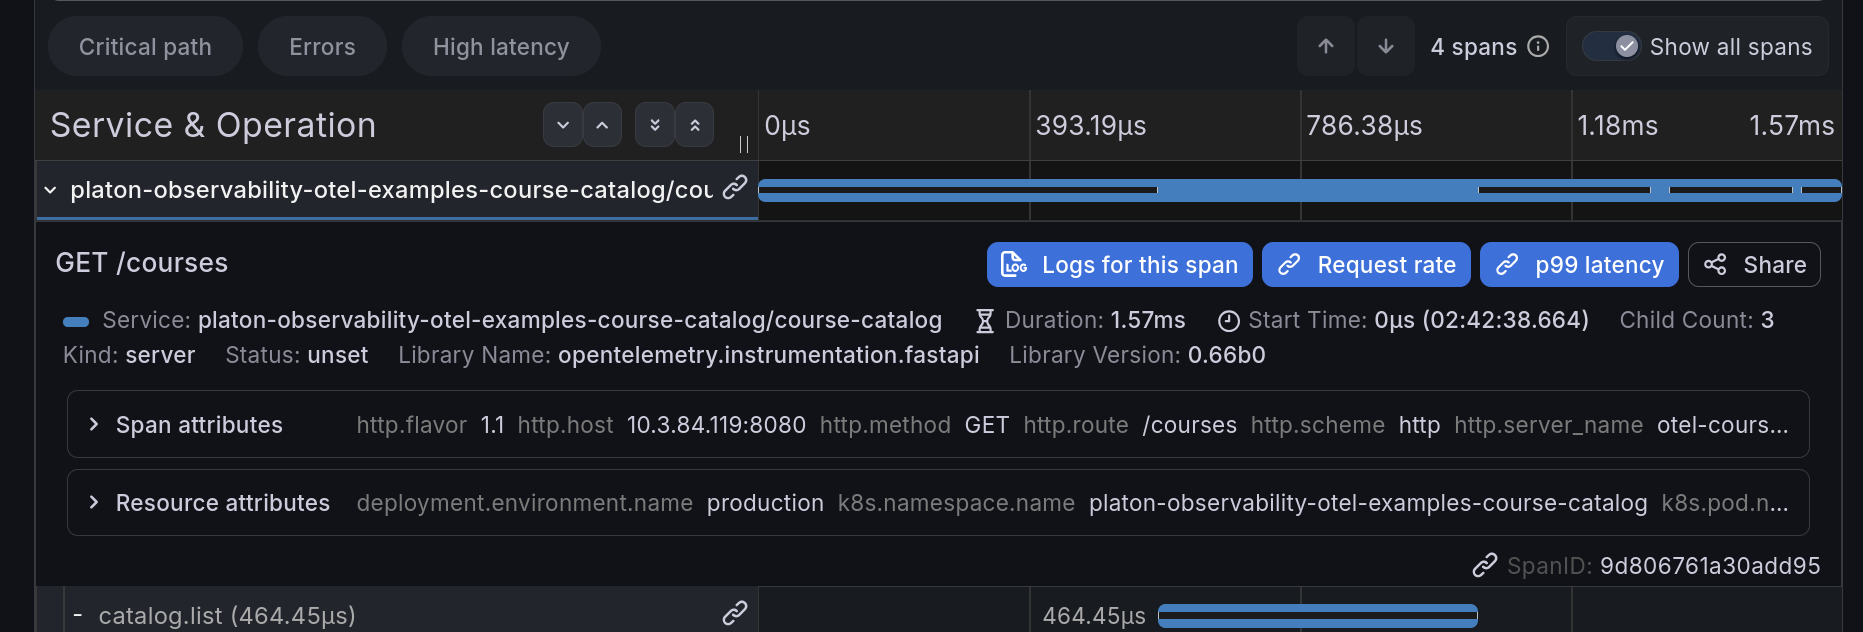
From a span to its logs. Select a span in a trace and click Logs for this span. Log lines are easier to read than a trace and often carry detail the span lacks, so this gives a better overview of what happened. The button shows every log line that the span's service wrote for the request, including lines from that service's other spans. Another service's lines appear when you select one of its spans.
-
From a trace to metrics. The Request rate and p99 latency buttons in the screenshot above show how the service was doing when the request arrived. They run queries built from span metrics, which Tempo derives from traces. Whether you get these queries, and which ones, is agreed between your team and Platon.
-
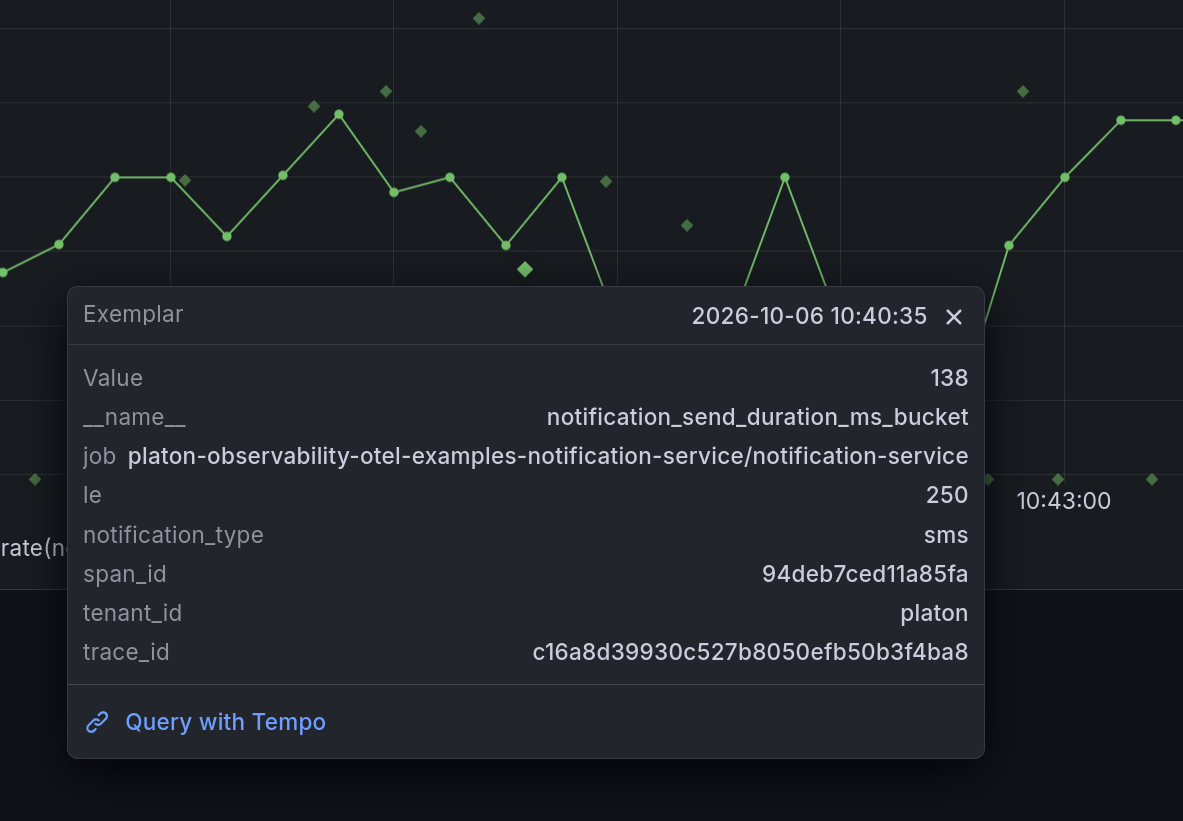
From a graph to a trace. To find out what made a request slow, turn on Exemplars in the query options. The graph then shows each exemplar, a data point that carries a trace ID, as a diamond. Click a diamond and choose Query with Tempo to open the trace behind that data point. If no diamonds appear, see When a link is missing.
Platon sets these links up per tenant when your team is onboarded for OpenTelemetry. If a link is missing and none of the causes under When a link is missing applies, ask the Platon team on #platon-observability.
When a link is missing
Each link depends on what your telemetry carries. When one doesn't show up, the cause is usually one of these:
- No "View trace" on a log line. Only lines written while a span is active carry a trace ID, so a line written outside a span, such as one from startup code, has none. Lines that PaaS Logging collects from stdout never get the trace ID as a field, even when the text contains one. The link needs logs sent over OTLP.
- "Logs for this span" shows nothing. The button finds the span's service by labels that stdout logs lack, so it needs logs sent over OTLP. It also shows nothing when no line carries the span's trace ID, because it shows only the lines that do.
- No exemplar diamonds on a graph. Some SDKs, including the Node.js SDK, produce no exemplars, so graphs of their metrics have none; see Metrics — Exemplars. Exemplars are attached only to a histogram's
_bucketseries, so a graph built from_countnever shows one. Only measurements taken while a sampled span is active get an exemplar that opens a trace. - No "Request rate" or "p99 latency" buttons. Platon sets up the queries behind these buttons per tenant, and not every tenant has them. Ask the Platon team on #platon-observability.
Setting up the telemetry itself is covered on PaaS Full Observability and External Services.
Where to start
For teams adopting OTel, enabling traces with auto-instrumentation is usually the best place to start. It takes little work, typically one SDK import per language, and gives you cross-service timing and a way to drill down into slow requests, which are hard to get any other way.
Auto-instrumented HTTP metrics give you the RED method (Rate, Errors, Duration) for every endpoint without custom code. Your logs are likely already working, and the logging instrumentation adds the trace ID to lines written inside a span.